Hello, this is Ryuta Hamamoto from TIMEWELL.
This is the sixth article in our FDE practice series. The first five covered the skills of collecting from the field. Interviews note down the nouns and verbs, observation confirms them, ethnography thickens their meaning, the KJ method turns them into structure, and video adds numbers. The "dictionary of nouns and verbs" appears in every one of those articles. This time I want to explain how that dictionary gets turned into a form an AI can traverse.
In an earlier article on the difference between FDEs and AI accompaniment I wrote that an agent cannot run until it has been taught the nouns and verbs. For an agent to "allocate an order," it has to hold, in a form a machine can read, what an order is in this company, what allocating means, and what comes before and after allocation. That form is an ontology. It is an intimidating word, but what it does is carve up the world in the company's own words and hand it to a machine. If you first want to check how far your own business vocabulary is in a form that can be handed to AI, take the AI literacy check.
What an ontology is: carving up the world in the company's own words
The word comes from philosophy, but in information science Tom Gruber defined it in 1993 as an explicit specification of a conceptualization: a shareable, explicit written account of what exists in a domain and how those things relate.1 In short, an unambiguous dictionary of a domain's nouns, verbs, and relationships.
Palantir put this idea at the center of its enterprise product. In its documentation, the ontology is a layer that sits on top of integrated data and connects it to its real-world counterparts, built from object types, properties, links, action types, and functions.2 Objects are the nouns, links the relationships, actions the verbs. The person who spent eight years as an FDE at Palantir lists "ontology" among the company's old internal terms,3 and the structure is visible: when an FDE brings the meaning of a business learned on site back into the product, the ontology is where it lands.
Why is this needed in the age of AI agents? Because agents act. An AI that only summarizes text can run on vague definitions of the company's words. But an agent that "allocates orders awaiting approval and issues shipping instructions" cannot move without knowing what awaiting approval means, what allocation is, and whose authority a shipping instruction requires. If it moves anyway, it allocates wrongly. The definitions of nouns and verbs are the basis of the agent's actions.
From transcripts to dictionary: extracting nouns, verbs, relationships, states, and exceptions
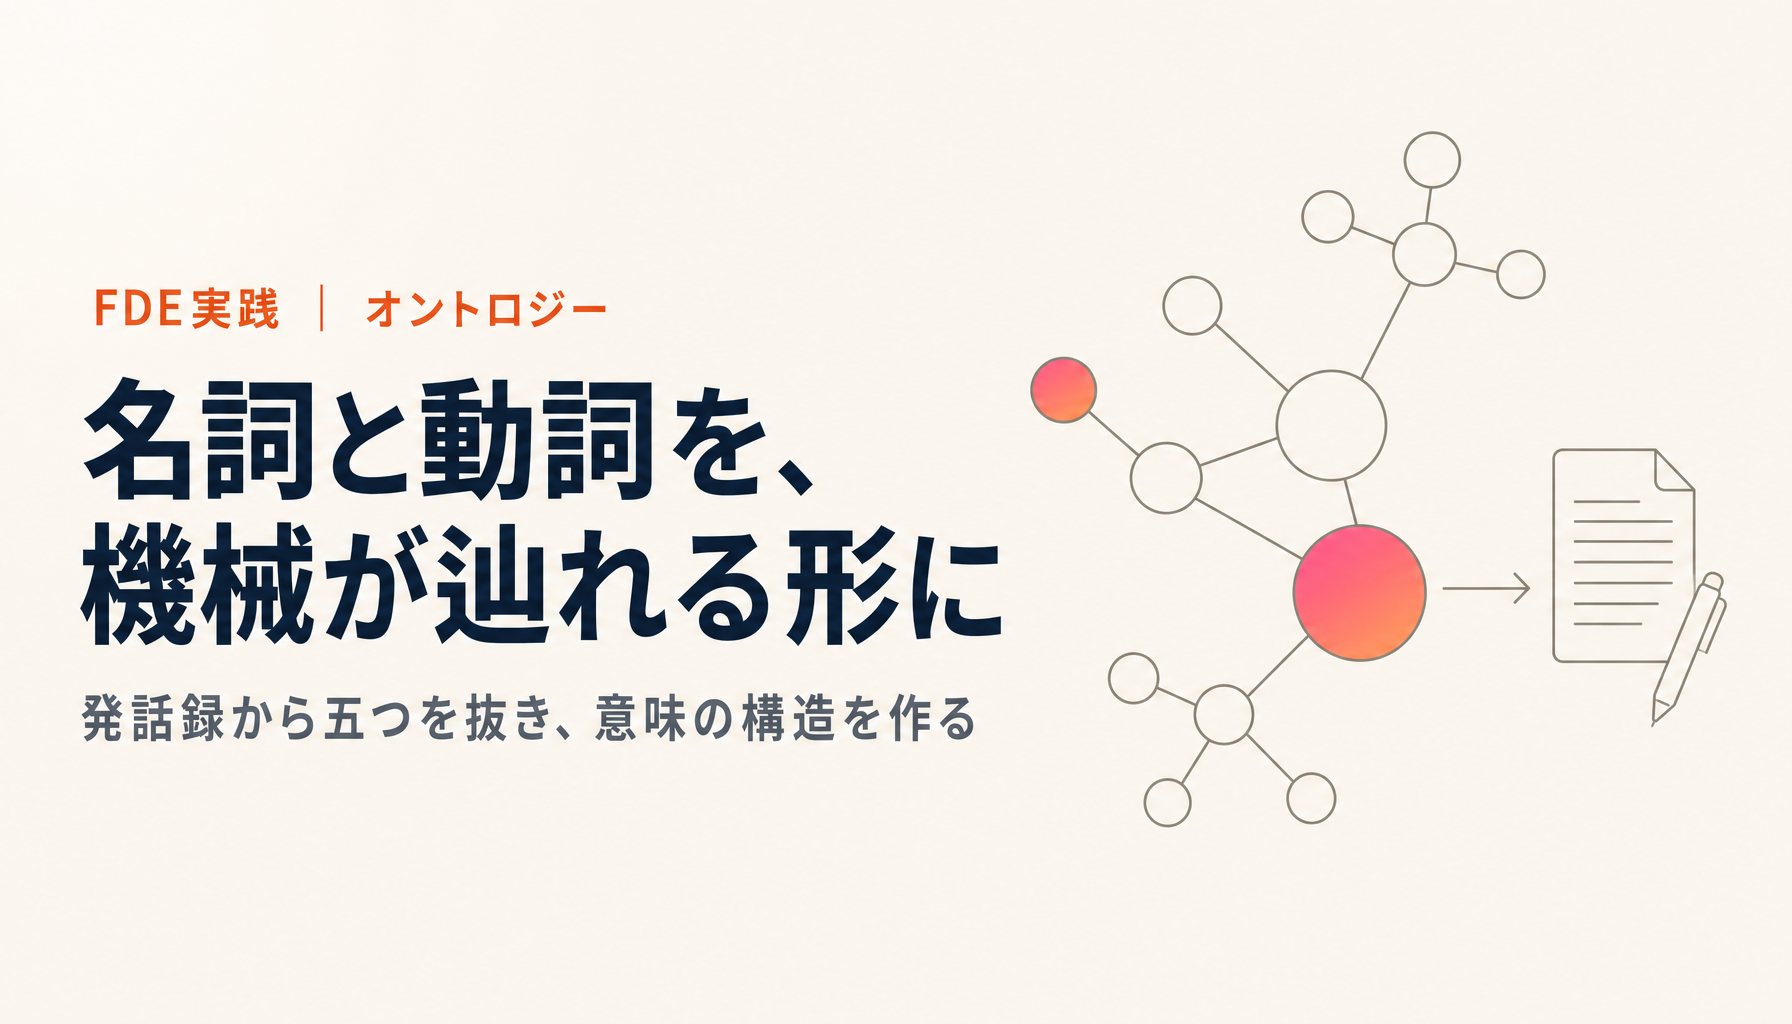
Here is the procedure. The material is everything gathered in the first five articles: interview transcripts, five-column observation records, three-layer ethnographic notes, KJ group names, and video counts. From these, extract five things.
| What to extract | What it is | Example from a transcript | How it goes in the dictionary |
|---|---|---|---|
| Nouns | Names of things used in this company | "When an order comes in, we first check inventory" | Order, Inventory |
| Verbs | What people do to nouns | "We allocate inventory and mark it as reserved" | Allocate (inventory to an order), Reserve (sales, verbally) |
| Relationships | How nouns connect | "Every order has a shipment attached" | An order has one or more shipments |
| States | Stages a noun can be in | "We don't touch anything awaiting approval" | Order states: received, awaiting approval, approved, shipped |
| Exceptions | Routes that differ from the usual, and their conditions | "When it's urgent the assistant manager stamps it" | Approver is the section manager, except for the urgent category, where it is the assistant manager |
Nouns are written in the company's own words, not translated into system terms. If "allocate" and "reserve" mean different things, they are two verbs. This is where the KJ group names pay off. The group name "in practice, approval is two-stage: the assistant manager's judgment and the section manager's stamp" becomes the definition of the verb "approve." The dictionary entry reads: "To approve means that the assistant manager judges and the section manager stamps." With the two stages written into the dictionary, the agent does not stop after the first.
Relationships and states are confirmed from observation and video. The transcript says every order has a shipment attached, but the screen recording may show orders marked complete with no shipment. In that case the relationship is corrected to "an order has a shipment, except sample shipments." The gap between what was said and what was observed raises the dictionary's precision.
Exceptions are the most important and the most easily lost. "When it's urgent the assistant manager stamps it" does not appear on a feature list, but it appears in the dictionary. Whether the agent parks an urgent order waiting for the section manager or routes it to the assistant manager is decided by that one line.
For extraction we use AI. It reads the transcripts and observation records and lists candidates for all five. A machine is faster at proposing: a few dozen nouns and verbs from a few hundred fragments in minutes. But a person fixes them, because the same word means different things in different departments. Sales' "reserve" and the warehouse's "reserve" are different actions, and machine extraction merges them. The dictionary writes "reserve (sales)" and "reserve (warehouse)" separately, with a rule for deciding which is meant from context. Only someone who thickened the meaning through ethnography can make that split.
Looking for AI training and consulting?
Learn about WARP training programs and consulting services in our materials.
Making the dictionary traversable: graphs and agents
Once the dictionary exists, it is put in a form a machine can traverse: a graph, with nouns as nodes and relationships as edges. States are node attributes, verbs are the operations permitted on a node, and exceptions are conditions on those operations.
The reason for this form is that agents do not just answer questions; they traverse and act. To answer "can this order ship?", the agent has to walk from the order node through its state (approved?), its relationships (is inventory allocated?), and its exceptions (does the urgent category require only the assistant manager?). Searching a pile of documents cannot do that walk. Combining large language models with knowledge graphs to answer questions that span an entire corpus was systematized in 2024 as GraphRAG.4 Our ZEROCK is a product that holds a company's knowledge in this form for agents to traverse, and the dictionary built on site goes straight into the product's structure.
This connects to what a16z wrote in January 2026 about reusable primitives. That essay describes the real FDE model as one built on reusable primitives, data models and workflow components, rather than on net-new features per customer.5 The ontology is the most basic of those primitives. "An order has states," "approval can have multiple stages," "exceptions branch on a category": these structures do not change from company to company. What changes is the names of the states, the number of stages, and the categories. So the structure lives in the product's standard schema and the names, stages, and categories are per-customer configuration. "Approval is two-stage," seen at three companies, becomes product schema; "in this company the urgent category goes to the assistant manager" becomes configuration. The pattern-or-branch sorting from the KJ article lands here, in the product's structure.
The details of how the agent is run are in the article on context engineering. Of everything passed to an agent as context, the dictionary is the part that changes least and hurts most when wrong.
How it differs from data modeling in contract development
Contract development also has a data-modeling step: identify entities, define relationships, design the database. Writing out nouns and relationships looks the same. Here is the difference.
| Aspect | Data modeling (contract development) | FDE ontology |
|---|---|---|
| Purpose | Design the system's database | Give an AI agent a basis for action |
| Source | Requirements document | Shop-floor speech, observation, video |
| Verbs and exceptions | Written separately as functional specs | Written with the nouns, with conditions |
| Updating | Frozen in the design phase | Weekly, from reactions to the working artifact |
| Ownership | The customer's database | Patterns in the product's standard schema, branches as customer extensions |
| Owner | The development side | The customer's side, so it can be updated after the FDE leaves |
The biggest difference is the treatment of verbs and exceptions. Data modeling handles nouns and relationships; verbs go into a separate functional specification, and exceptions end up under "other" in the remarks. An ontology writes verbs and exceptions in the same place as the nouns, with conditions. For an agent, the verb "approve" and the exception "urgent goes to the assistant manager" matter as much as the noun "order."
The other difference is the owner. The owner of a contract data model is the development side, and changes are a maintenance contract. An FDE ontology puts the owner on the customer's side. When the person on site edits the dictionary because the approver for the urgent category has changed, the agent's behavior changes. The FDE leaves once that state exists. The FDE organization AWS launched in June 2026 puts the customer's ability to run things themselves at the end of the engagement at the center of its design;6 for us, the condition for running on their own is that the dictionary's owner is on site.
On site: update the dictionary weekly and reflect it in the working artifact
The procedure runs weekly. Monday to Thursday, collect on site. Friday, build groups with the KJ method, extract the five things from the group names, and update the dictionary. The following Monday, have the agent read the updated dictionary and put down a working artifact. Ask the person "what is different?" and fix the dictionary. That loop is one week.
The dictionary is versioned. It is normal for the definition of "approve" to move from "the section manager stamps" in week one, to "the assistant manager judges and the section manager stamps" in week two, to "urgent category: assistant manager only" in week three. Keeping the versions lets you trace afterward why the agent's behavior changed. When the person says "it behaves differently from last week," showing the dictionary diff ends the explanation.
And the dictionary's owner is decided. While our engineers are on site we update it, but before we finish we hand it to the person on site. What is handed over is the procedure for extracting the five things, the way of separating meanings by department, and the way of keeping versions. When the person can edit "the approver for the urgent category changed from the assistant manager to the team lead" on their own, the FDE is no longer needed. Not being needed is the completion condition for this step.
What we do and where it stops
Let me be honest. A dictionary is a living thing and is never finished. The company's words change, the organization changes, exceptions multiply. A dictionary we took home being stale six months later is what happens when we fail to place the owner on site. That is why the handover is the completion condition.
There are limits. AI extraction goes as far as proposing candidates. "Same word, different meaning" and "different words, same meaning" are invisible to a machine. When "reserve" appears forty times in the transcripts, how many are sales and how many are warehouse is sorted by the person who was there. And the dictionary cannot exceed the quality of the fragments collected. If the interviews happened only in meeting rooms, the dictionary is a dictionary of the process as it should be, and the agent stalls on the process as it is. That is one more reason the skills in the first five articles come first.
Finally, the relationship to our product, stated plainly. Our ZEROCK holds this dictionary as structure. So our FDEs grow the product as they build the dictionary. That is not a conflict of interest; it is the FDE model itself. If the learning did not return to the product, this would be contract work. But the dictionary's owner is the customer and its contents belong to the customer. What returns to the product is the structure, not the company's own nouns and verbs.
Summary
The dictionary of nouns and verbs collected on site is not usable by an agent as a dictionary. Extract nouns, verbs, relationships, states, and exceptions from transcripts and observation records, put them in graph form, and let the agent traverse them. That is an ontology: carving up the world in the company's own words and handing it to a machine.
It differs from contract data modeling in writing verbs and exceptions alongside the nouns with conditions, updating weekly, returning patterns to the product's standard schema while holding branches as customer extensions, and placing the owner on the customer's side. The FDE no longer being needed is the completion condition.
If you want your business vocabulary in a form agents can traverse, or are looking for a partner to turn your shop-floor dictionary into product structure, take a look at the WARP program or talk to us. The next article puts all of these skills into a single week: an FDE's week, from day one to Friday.
Footnotes
-
Gruber, T. R. (1993). A translation approach to portable ontology specifications. Knowledge Acquisition, 5(2), 199–220. DOI: 10.1006/knac.1993.1008. "An explicit specification of a conceptualization" is from this paper ↩
-
Ontology overview (Palantir Foundry documentation). The description of the building blocks is my summary of this document ↩
-
Reflections on Palantir (Nabeel S. Qureshi, October 15, 2024) ↩
-
Edge, D., et al. (2024). From Local to Global: A Graph RAG Approach to Query-Focused Summarization. arXiv:2404.16130 ↩
-
The Palantirization of everything (Marc Andrusko, a16z, January 16, 2026). The point about reusable primitives (data models, workflow engines, UI components) is from this essay ↩
-
AWS invests $1 billion to embed AI forward deployed engineers with customers (Amazon, June 30, 2026) ↩